Multi-region resilience
Learn about multi-region deployment and choose the right strategy for your recovery and resilience needs.
About
Camunda provides a structured multi-region resilience framework for Self-Managed Orchestration Cluster deployments.
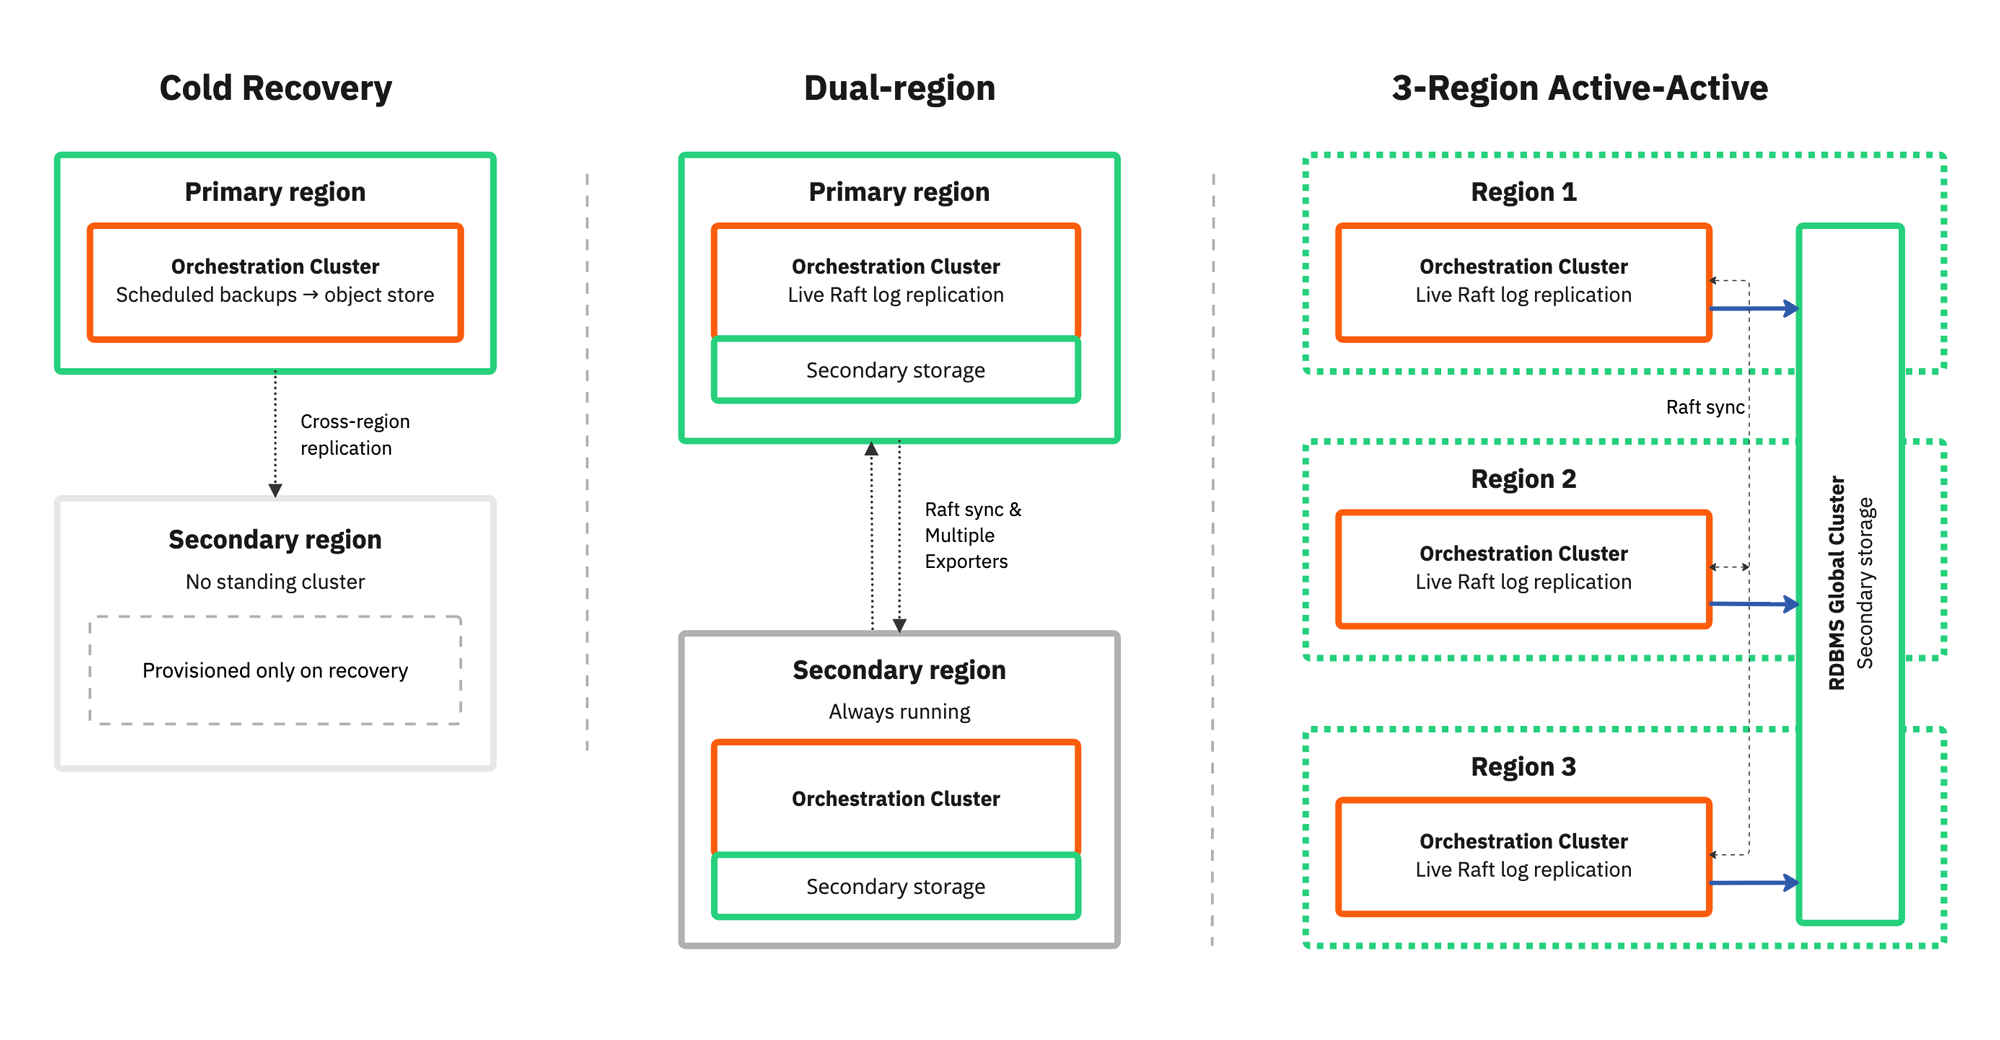
-
Cold Recovery: Camunda's lowest-cost multi-region configuration uses scheduled cross-region backups and a manual restore procedure to recover from complete primary-region loss. Recovery measured in hours is operationally acceptable.
-
Dual-Region: Dual-region deployment with continuous replication. A full Camunda Orchestration Cluster runs continuously in both a primary and secondary region.
-
Multi-Region RDBMS: One Orchestration Cluster runs active-active across two or more regions, and survives a region loss with three or more. A relational database (RDBMS) with cross-region replication holds the secondary storage. Losing one region preserves the cluster quorum. You must fail over the database writer if the lost region held the writer.
Get started: choose your strategy
Choosing the right recovery strategy is determined by how critical your process automation is to your business. How much downtime and data loss can you tolerate, and what compliance obligations do you have?
First, determine how critical your workload is:
| If your business can accept the following outcome: | Choose this option |
|---|---|
| Recovery measured in hours, and minutes to hours of data loss. | Cold Recovery |
| Recovery in ~15 minutes, with no data loss, and audit-ready posture. | Dual-Region |
| Processing continues after a single region loss, and you can run without Optimize. | Multi-Region RDBMS |
What each strategy asks of you:
- Cold Recovery is a manual procedure built on the backup and restore guide. There is no reference architecture. Validate the procedure in your own environment.
- Dual-Region includes a reference architecture and an operational runbook, with documented Recovery Time Objective (RTO) and Recovery Point Objective (RPO) targets. A region loss stops processing until an operator runs the failover.
- Multi-Region RDBMS, with three or more regions, keeps processing through a region loss with no Zeebe operator step. The database handles secondary-storage replication. In exchange, it costs a third region of capacity. Optimize is unavailable, because Optimize requires Elasticsearch or OpenSearch instead of a relational secondary storage.
Comparison of multi-region resilience
The following table provides a detailed comparison of the available multi-region deployment options:
| Consideration | Cold Recovery | Dual-Region (Elasticsearch) | Multi-Region RDBMS |
|---|---|---|---|
| Regions | One, plus cross-region object storage | Exactly two | Two or more. Three or more to keep processing through a region loss |
| Recovery time (RTO) | ~1–4 hours | ~15 minutes | With three or more regions, no Zeebe recovery procedure. The window is a Raft re-election plus your own client and traffic failover, plus the database writer promotion if the lost region held the writer |
| Data loss (RPO) | 15 min – 4 hours (backup-interval dependent) | 0 minutes | 0 minutes for engine state, and for secondary storage once replay completes under the documented replication monitoring |
| Failover mode | Manual, operator-initiated | Manual, operator-initiated | With three or more regions, automatic for Zeebe. Manual for the database writer, and only if it was in the lost region |
| Secondary storage | Elasticsearch or OpenSearch, restored from backup | Elasticsearch, one cluster per region | RDBMS, one database replicated by the database itself |
| Architecture | Scheduled backup to cross-region object storage. Manual restore into a secondary region | Orchestration Cluster running in both regions. Dual-region exporters. Manual failover | One Orchestration Cluster across every region. One exporter. Zone-aware partition placement, where this reference layout maps one zone to one region. A zone can also be an availability zone |
| Typical use case | Low-criticality production; environments where hours-long recovery is acceptable | Enterprise production workloads that must survive a region failure | Workloads that cannot pause while an operator runs a failover |
| Optimize | Supported | Supported | Not available, Optimize requires Elasticsearch or OpenSearch |
| Compliance fit | Basic business continuity management (BCM) requirements | Certified, auditable region-recovery posture with a published runbook | Auditable region-recovery posture with a published runbook, for organizations that also require continuous processing |
| Relative cost | $ (lower cost): Object storage only; no standing second region | $$$ (higher cost): Orchestration Cluster running across both regions with extra capacity to sustain load in case of Region failure, plus cross-region traffic | $$$$ (highest cost): Orchestration Cluster running across three or more regions, plus cross-region traffic |
Cold Recovery RTO and RPO targets are bounded by data volume, backup frequency, and operator restore speed. Treat published ranges as planning targets, not contractual commitments.
Dual-Region RTO is based on internal operational tests. Actual times may vary depending on your environment, level of automation and the specific manual steps performed during recovery. See Dual-Region for a phase-by-phase breakdown.
With three or more regions, Multi-Region RDBMS removes the recovery procedure, not the recovery window. A published RTO figure would not be meaningful here. Most of the elapsed time comes from your client timeouts, your traffic routing, and your database failover, not from the architecture. Measure the actual recovery window, including client reconnection, with a real failover test in your environment.
Multi-Region RDBMS reaches RPO 0 for engine state, and for secondary storage only under the replication conditions you configure. See recovery objectives.